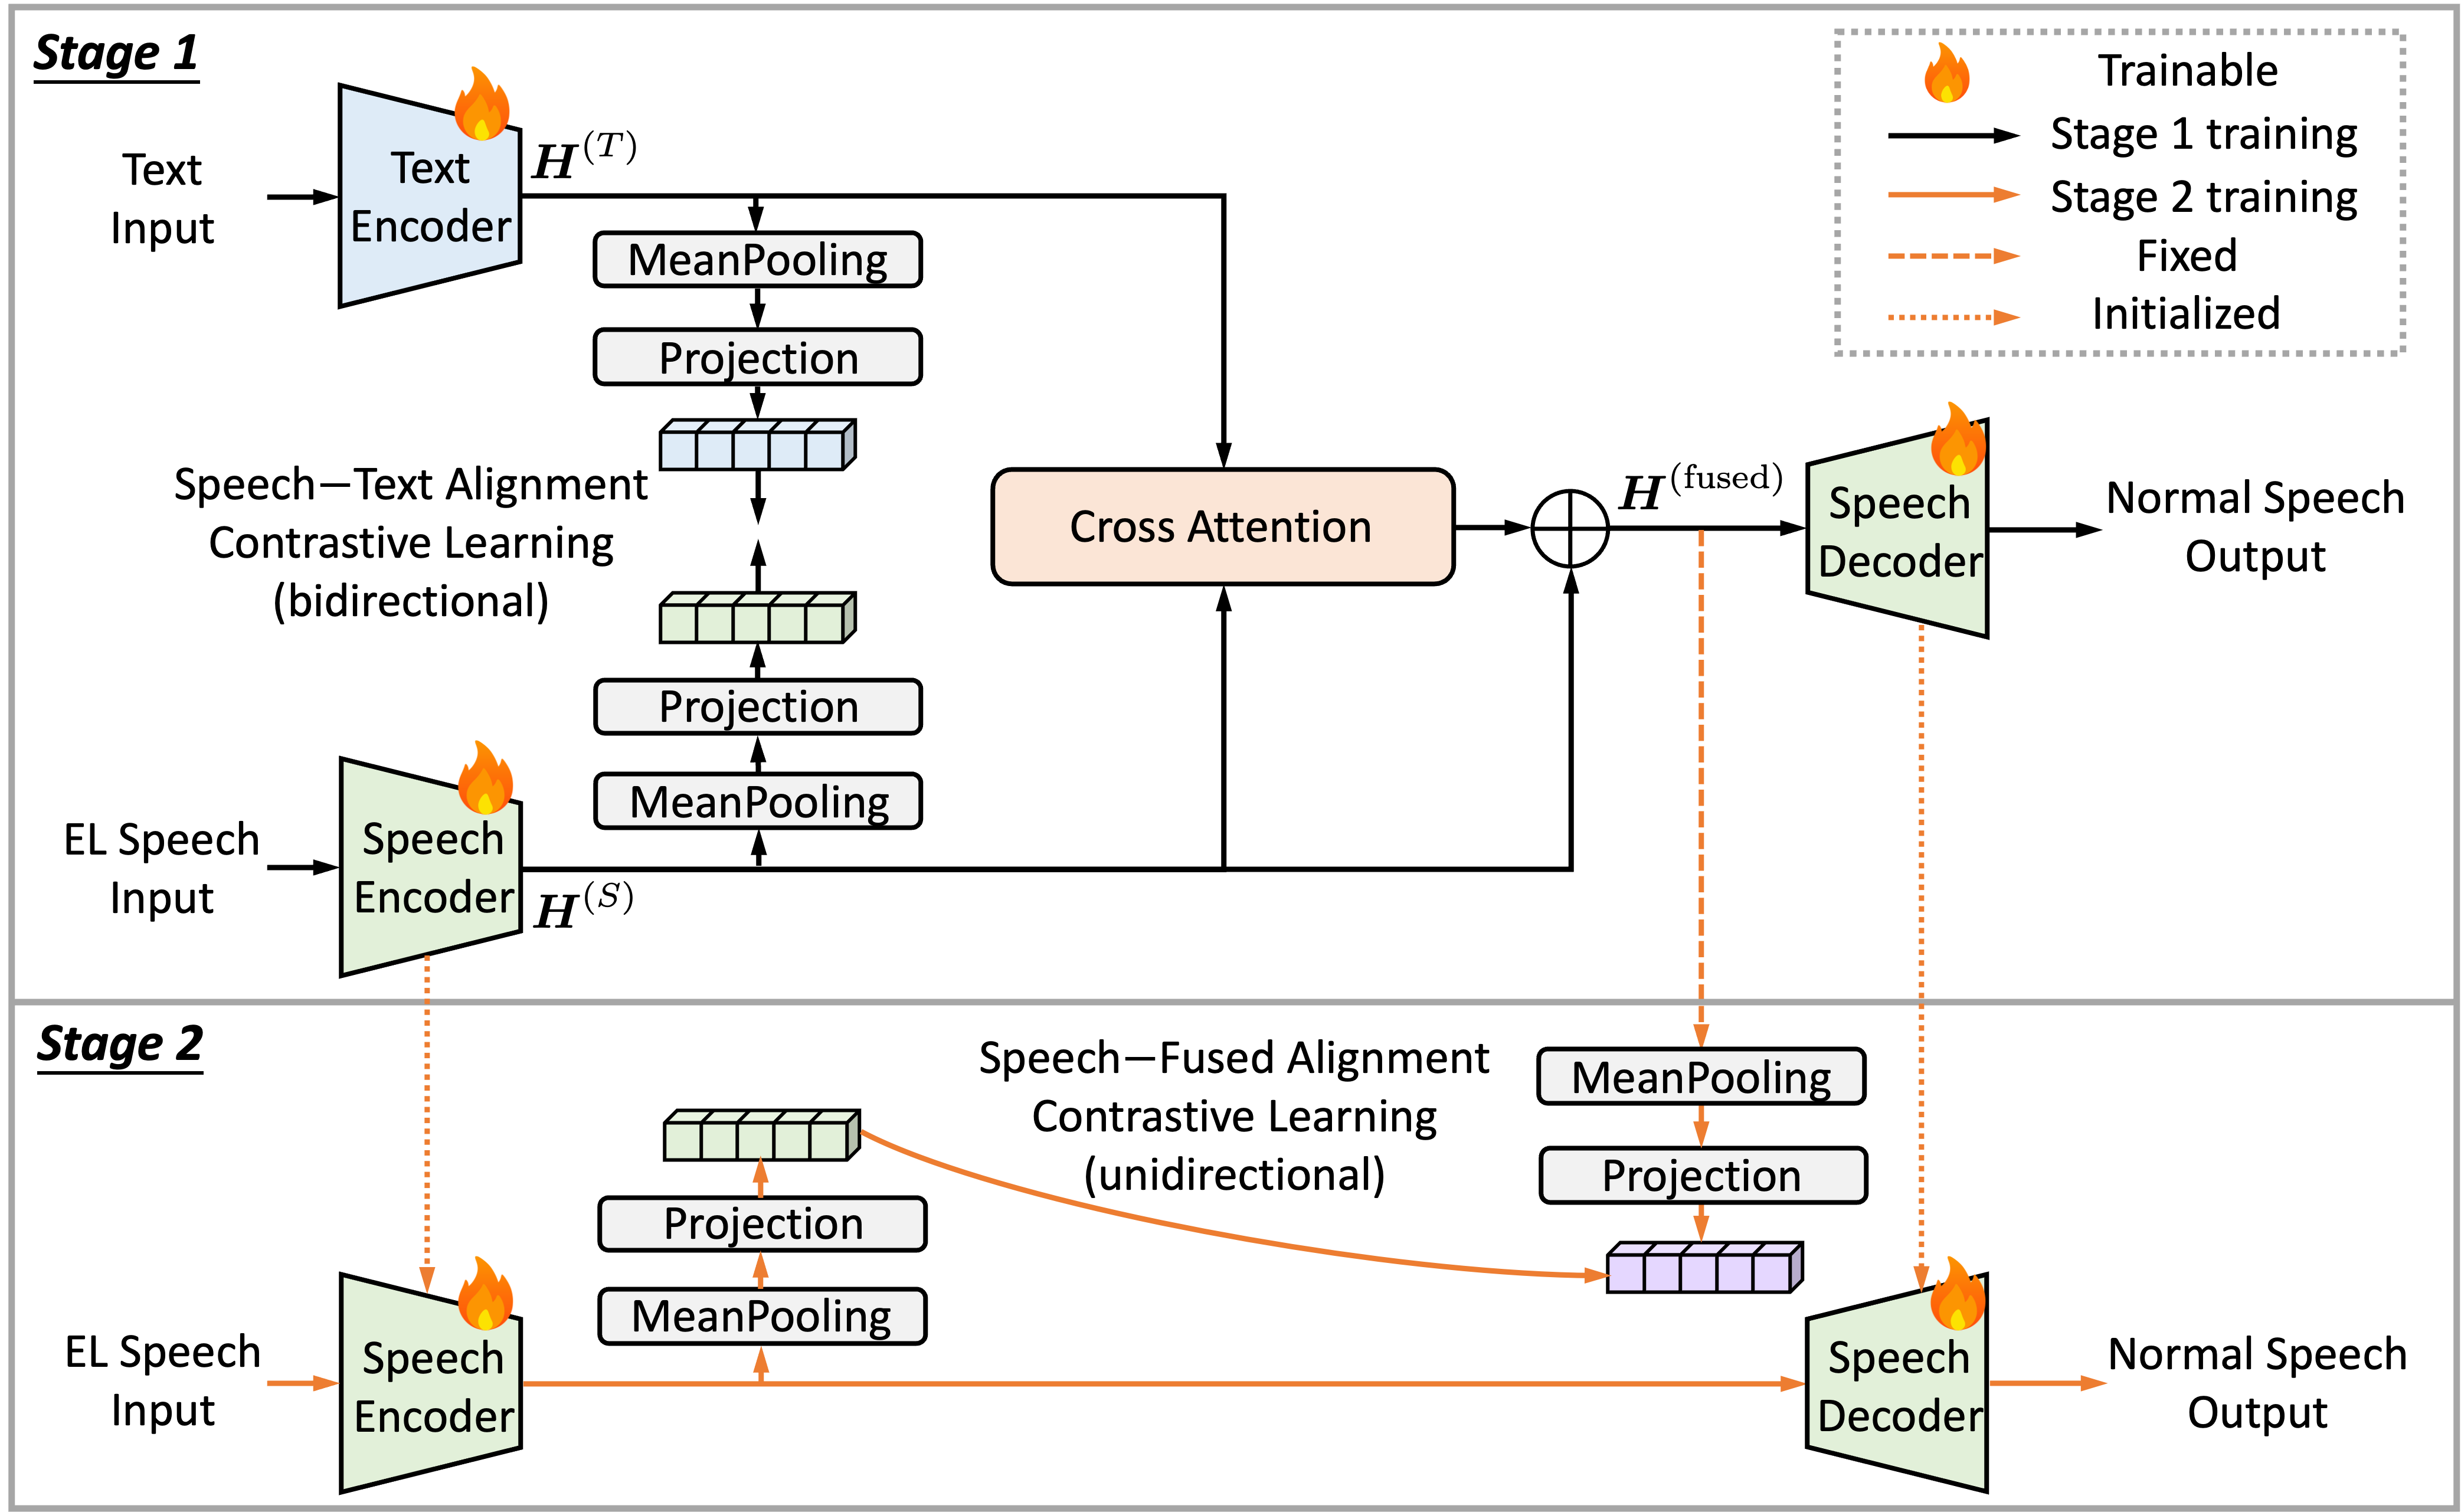
Abstract:Electrolaryngeal (EL) speech suffers from severe acoustic mismatches with normal speech, resulting in degraded naturalness and intelligibility. These mismatches also make sequence-to-sequence voice conversion struggle to learn robust intermediate representations, hindering EL-speech-to-normal-speech conversion (EL2SP) performance. To address this, we propose a novel multimodal contrastive representation learning framework to 1) achieve richer multimodal-representation learning, and 2) facilitate the transferability of multimodal representations to speech-only EL2SP. First, EL speech and text representations are fused to learn multimodal representations for target speech generation, during which cross-modal contrastive learning is employed to encourage a semantically consistent speech--text representation space. Next, the fused representations are treated as a fixed target to guide speech-only representation learning through cross-stage contrastive learning, enabling multimodal knowledge to be transferred to the EL2SP task while preserving architectural and inference simplicity. Experimental results demonstrate that the proposed method consistently outperforms both the speech-only and multimodal-based baselines.
Main concept
Dataset
Patient 1 and Patient 2 datasets were used to evaluate experimental systems for EL2SP.
Systems
EL speech, Normal speech: Original source EL and target normal speech as the reference.
S-VC: Speech representation learning by first conducting pretraining then conducting two-stage fine-tuning with the synthetic data and original EL2SP dataset.
MR-VC: Motimodal representation learning method trained with the synthetic data, original EL2SP dataset, and text data.
MCRL-VC: Proposed motimodal representation learning method using two-stage cross modal contrastive learning and trained with the synthetic data, original EL2SP dataset, and text data.
Conversion Samples on Patient 1
Transcription: 明けまして、おめでとうございます。 (a ke ma shi te, o me de tou go za i ma su.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription: 世界的なヴァイオリニストを、招待する。 (se ka i te ki na va i o ri ni su to o, shou ta i su ru.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription: 使う道具は、ペンではなくて、万年筆であった。 (tsu ka u dou gu wa, pen de wa na ku te, man nen hi tsu de a tta.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription: おばあちゃんに、お茶を一杯、いれてあげる。 (o ba a chan ni, o cha o i ppai, i re te a ge ru.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Conversion Samples on Patient 2
Transcription: 保証が 沢山あるものにします。 (ho shou ga ta ku san a ru mo no ni shi ma su.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription: 日本の民芸品です。(ni hon no min gei hin de su.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription:202便をキャンセルしたいのですが。 (ni hya ku ni bin o kya n se ru shi ta i no de su ga.)
EL speech
Normal speech
Reference:
S-VC
MR-VC
MCRL-VC
Conversion:
Transcription: 違うバスに乗ってしまったようです。 (chi ga u ba su ni no tte shi ma tta you de su.)